
How to Generate Schema Structured Data: A Complete Guide
The short answer
Schema structured data turns webpage facts into machine-readable code. Learn how to choose the right generator, maintain accuracy, and validate deployments.
Schema structured data is a snippet of code that describes the facts on a webpage using a standardized format. It organizes titles, authors, publication dates, prices, addresses, and other details into fields that search systems can parse easily.
When creating Schema for the first time, many teams open an online generator, pick a template, fill in the blanks, and paste the code into their website. While this produces a block of code, it ignores three fundamental questions:
- Which Schema type actually fits the page?
- Do the structured properties match what visitors see on the live page?
- Can search engines properly extract and read the code once published?
If any of these three areas are neglected, the code may pass a basic syntax check while remaining entirely ineffective in search results.
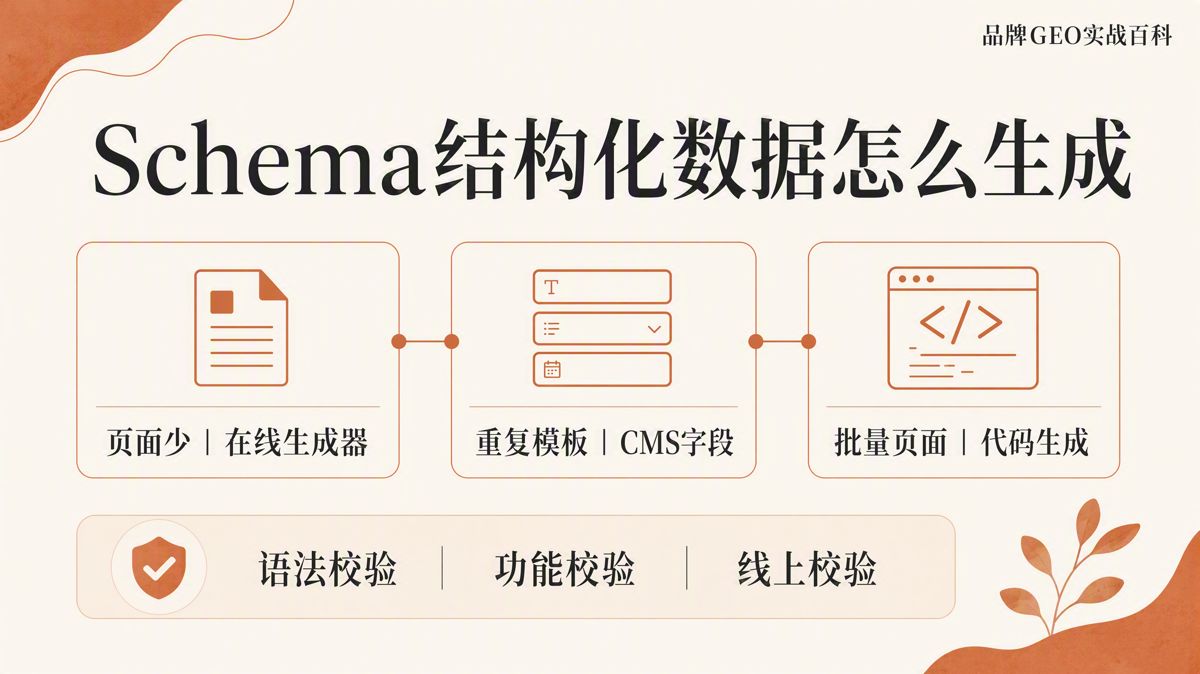
Here is a straightforward framework for choosing an implementation method:
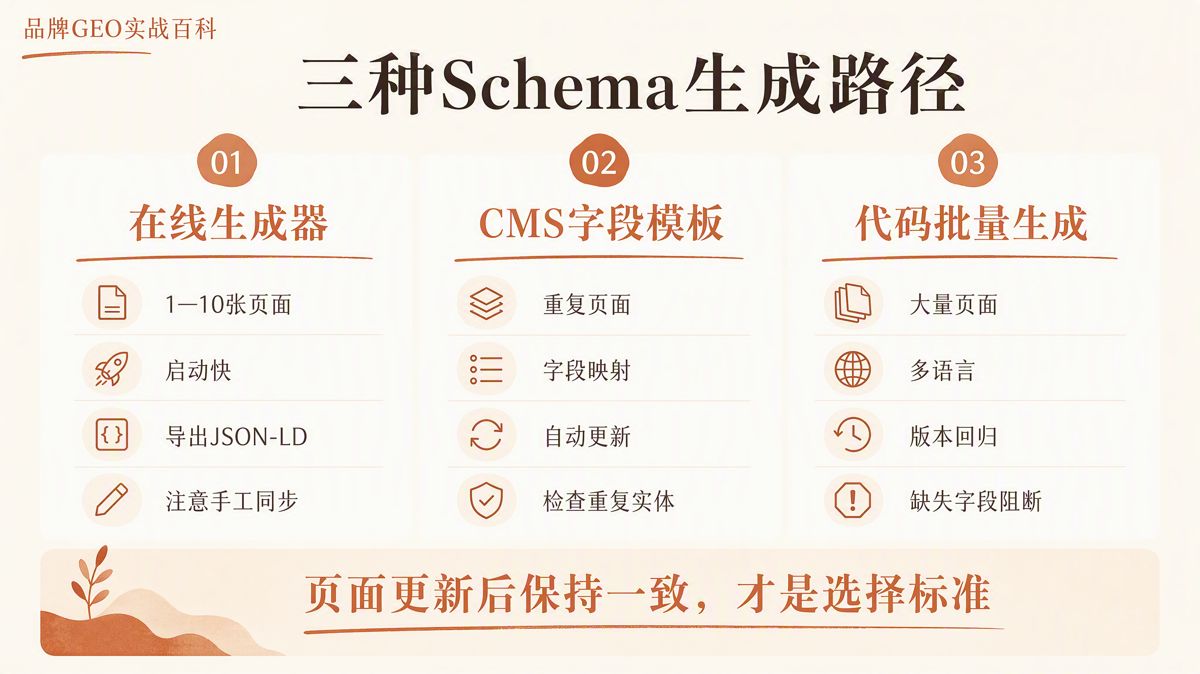
- A few static pages: Use an online Schema generator.
- Growing page sets (articles, products, location pages): Use CMS (Content Management System) plugins or automated page templates.
- Large-scale databases (e-commerce catalogs, knowledge bases, multilingual portals): Generate structured data programmatically via build pipelines.
- Across all methods: Always run a three-stage validation covering Schema syntax, search engine feature eligibility, and live production URLs.
A generator formats fields and outputs markup, but it cannot audit your facts, choose the appropriate entity type, or guarantee rich results, higher rankings, or citations by generative AI engines.
Rich results are enhanced search engine listings that display additional visual details such as images, pricing, ratings, or operational hours.
What Is Schema Markup?
A standard webpage presents information visually for human readers. Structured data reorganizes those exact same facts so machines—including search engine crawlers—can interpret them unambiguously.
For example, a published article contains a headline, author, publication date, last updated date, featured image, and body text. Structured data packages these details under the Article type.
Different pages require different types:
- Corporate homepages:
Organization(describes a company or legal entity) - Storefront pages:
LocalBusiness(describes a physical business location) - Product pages:
Product(describes an individual item or SKU) - Editorial posts:
Article(describes written content)
These types and properties are governed by Schema.org, the shared vocabulary registry used across search platforms.
Keep in mind that while Schema.org lists hundreds of types and properties, search engines only provide rich results for a specific selection. The existence of a type on Schema.org does not guarantee that search engines support enhanced search appearances for it.
What a Schema Generator Actually Does
A typical Schema generator handles three basic tasks:
- Selects the target schema type for your page.
- Maps your inputs to corresponding property fields.
- Exports the markup in JSON-LD, Microdata, or RDFa format.
JSON-LD is a structured data format packaged inside a standalone script element.
Microdata and RDFa are alternative formats that embed schema attributes directly into existing HTML tags. HTML is the markup code that builds the structure and content of a webpage.
All three formats express structured data effectively. The difference lies in where the markup lives within your code and how simple it is to maintain over time.
Why Most Websites Choose JSON-LD
JSON-LD sits inside a dedicated HTML script block:
<script type="application/ld+json">
</script>
Because it does not require editing individual HTML tags throughout the page body, you can maintain your visible content and structured data independently. JSON-LD also makes it easier to define nested relationships between multiple entities on the same page.
Google Search supports JSON-LD, Microdata, and RDFa. However, Google officially recommends JSON-LD whenever technically feasible. It is easier to deploy dynamically at scale and less prone to manual errors when page templates change.
That does not mean Microdata and RDFa are invalid. If an older site already relies on Microdata or RDFa without technical errors or missing fields, there is no need to rebuild the entire codebase just to switch formats.
Choose your format based on your operational reality:
- New sites or modern templates: Prioritize JSON-LD so developers can manage field mappings centrally.
- Legacy sites with functional Microdata or RDFa: Keep the current format unless you encounter missing features or data inaccuracies.
The format is simply the container. The priority is keeping the structured markup in sync with on-page facts.
Gather Page Facts Before Generating Code
Do not open a generator and search for values on the fly. Build a field inventory first. Document what each value is, where it lives in your system, and who maintains it.
Your inventory should include:
- The page URL
- The Schema type
- The primary entity name
- Headline or title
- Author or publisher
- Published date and modified date
- Image URLs
- Meta description or summary
- Canonical URL (the preferred version of the URL recognized by search engines)
- Type-specific fields (e.g., pricing, physical address, business hours, FAQ items)
Every field must come directly from content visible on the page or from CMS fields that update automatically alongside the page.
If you type values manually into a third-party generator, any subsequent update to the page will leave your schema out of sync—showing outdated titles, old prices, wrong dates, or dead image links. The markup may remain syntactically clean, but it no longer describes the live page.
Structured data must mirror on-page content. Features that are invisible to users, expired prices, fabricated reviews, or misleading claims are policy violations, regardless of whether the code validates.
Define Relationships Between Entities
A single URL often contains an article, an author, a publishing company, and the webpage itself. Across your site, the same parent organization will be referenced repeatedly.
If every page creates an isolated company object with no shared reference, search engines have to guess whether those references belong to the same entity.
To resolve this, assign a permanent @id—a stable URI that serves as the global identifier for that specific entity. When the same organization appears across blog posts, product pages, and contact pages, reference the identical @id.
Separate your authors, publishers, product brands, and webpage containers into distinct entities, then connect them via linking properties. Do not collapse distinct entities into a single generic object, and do not recreate unconnected duplicate entities on every page.
For a Few Static Pages: Use Online Generators
If you manage a small, static website (1 to 10 pages), an online generator is often the fastest route. Pick your type, fill in your verified facts, export the JSON-LD snippet, and insert it into your page templates or CMS head section.
Online tools require minimal technical setup, making them useful for exploring available properties and building reference templates. When evaluating a tool, look for three features:
- Complete raw code export.
- Support for your required Schema types.
- Full access to edit both required and recommended fields.
Avoid tools that only preview visual snippets without allowing you to copy or export raw code.
The main limitation of manual generators is version control. If a headline, price, or image changes on the site, manual code will not update on its own.
Once your site exceeds a dozen pages or uses shared templates, manual copy-pasting leads to missing properties and outdated facts. At that stage, switch to dynamic field extraction.
For Growing Page Types: Use CMS Plugins or Dynamic Templates
Websites that regularly publish articles, launch products, or add regional locations should generate structured data through CMS plugins or dynamic layout components.
These systems pull on-page titles, authors, dates, featured images, and custom database fields directly, injecting them into a standardized JSON-LD template. When a writer or editor updates an article, the structured data updates automatically.
When choosing a plugin or template engine, evaluate how it handles technical edge cases:
- Can CMS fields map accurately to standard Schema properties?
- Does the system support your specific URL structures and page layouts?
- Can editors override schema fields for specific one-off pages?
- Can developers inspect and export the raw rendered markup?
- Does the tool support automated re-validation after plugin updates?
Automated generation does not eliminate the need for QA. Fallback authors, placeholder images, empty properties, and stale values still require regular manual audits.
Watch out for duplicate markup. A theme, an SEO plugin, and a custom tracking script might all inject Schema for the same entity simultaneously. If one source outputs an old price and another outputs the current price, search engines encounter conflicting signals.
Verify that your rendered HTML contains a single, unified entity graph rather than competing code blocks.
For Large Sites: Generate Schema Programmatically
E-commerce stores, extensive knowledge bases, directory platforms, and multilingual sites require programmatic generation integrated into their core software.
Developers write routines that query product databases or API endpoints, generate dynamic JSON-LD blocks based on page types, and embed schema tests directly into build or continuous deployment pipelines.
A reliable programmatic setup should meet four requirements:
- Fail builds or alert developers when required Schema fields are missing.
- Generate consistent canonical URLs and stable
@ididentifiers. - Automatically swap staging and test domains for production domains.
- Trigger regression tests across all related templates when schema templates change.
Maintain version logs of your schema builds so you can trace what markup was served on any specific release date.
Writing custom code does not give you license to invent non-standard Schema types or properties. Always adhere to Schema.org standards and target search engine guidelines. Code handles data assembly; technical teams must ensure policy compliance and data accuracy.
Before pushing programmatic templates live, check these technical details:
- Are special characters (quotes, backslashes, ampersands) properly escaped?
- Are null or empty values excluded cleanly rather than outputting empty strings?
- Are multi-value fields formatted correctly as JSON arrays?
- Do multilingual URLs pull localized field values?
- Are all canonical URLs and image paths fully resolved and publicly accessible?
- Have all development or staging domains been replaced with production URLs?
A template bug at this level can instantly break structured data across thousands of indexed URLs.
Anatomy of a JSON-LD Snippet
Here is a simplified example of an Article schema snippet. It illustrates structure only; do not copy it verbatim into your site:
{
  "@context": "https://schema.org",
  "@type": "Article",
  "headline": "The exact title displayed on the live page",
  "datePublished": "2026-08-11",
  "dateModified": "2026-08-11",
  "author": {
    "@type": "Person",
    "name": "The author name displayed on the live page"
  },
  "mainEntityOfPage": "https://www.example.com/article"
}
Key components:
@context: Declares that the markup uses the Schema.org vocabulary.@type: Declares the specific entity type being described (in this case, anArticle).headline: The title of the article.datePublished: The original ISO 8601 publication date.dateModified: The date the article was last updated.author: The nested entity defining the writer.mainEntityOfPage: The canonical URL of the article container.
In production, you will add required and recommended fields based on your search engine targets. Populate all values dynamically from your database or CMS—never hardcode static values into a shared template.
Three Validation Steps You Must Run After Generation
Generating markup is only step one. Before relying on your structured data, run these three distinct validation checks in order.
Step 1: Validate Schema Syntax
Use the Schema.org Markup Validator to test your raw code. This tool verifies:
- Proper JSON formatting (balanced brackets, quotes, commas).
- Recognized property names according to Schema.org vocabulary.
- Valid data types (strings, integers, dates, URLs).
- Proper nesting and references between connected entities.
Core question: Is this valid Schema.org code?
Step 2: Test Search Engine Feature Eligibility
Next, use search engine testing tools—such as Google's Rich Results Test—to verify whether the page qualifies for enhanced SERP features.
This tool checks whether the entity type is supported for search enhancements, whether all mandatory properties are present, and whether your layout follows technical guidelines.
Passing this test confirms your page is technically eligible for rich results; it does not guarantee the search engine will display them for every query.
Core question: Does this page qualify for search enhancements?
Step 3: Inspect the Live Production URL
After deploying, run the live URL through a production URL inspection tool (such as Google Search Console's URL Inspection tool) to evaluate the rendered page.
Verify that:
- Search crawlers successfully parse the JSON-LD script from the live DOM.
- Rendered properties match the visible text on the page.
- Markup is not being stripped by caching layers, CDNs, or client-side JavaScript issues.
- The page is not blocked by robots.txt rules, noindex tags, or crawl errors.
Core question: Can search engine crawlers access and read the code on the live site?
These three checks serve different purposes and cannot replace one another:
- Valid syntax does not guarantee search engine feature support.
- A passing rich results test does not mean the code is live on production.
- Successful crawler rendering does not guarantee that enhanced features will appear in search results.
Six Tool Categories and How to Use Them
| Tool Category | Best For | Required Capabilities | Key Deliverable |
|---|---|---|---|
| Online Generators | 1–10 static pages | Type selection, field editing, raw code export | Clean JSON-LD file |
| CMS Plugins / Modules | Recurring page templates | Dynamic field mapping, template coverage, per-page overrides | Automated on-page markup |
| Custom Script Pipelines | Large product catalogs or multilingual portals | Version auditing, automated testing, environment checks, missing-field alerts | Programmatic deployment logs |
| Schema.org Validator | All implementations | Syntax checks, vocabulary validation, entity link checks | Syntax validation report |
| Feature Testing Tools | Pages targeting rich results | Supported type checks, mandatory field checks, policy validation | Eligibility test results |
| Live URL Inspection Tools | Live production URLs | Crawl checks, rendered DOM inspection, indexation status | Production verification record |
If your team manages a standard corporate site, use an online tool to map out required fields, then embed those specifications into your CMS templates.
If your site publishes new articles, launches products, or updates physical locations on a weekly basis, connect those properties directly to your CMS database.
Measure success not by the number of tools you use, but by whether your structured data stays synchronized whenever on-page content changes.
An End-to-End Implementation Workflow
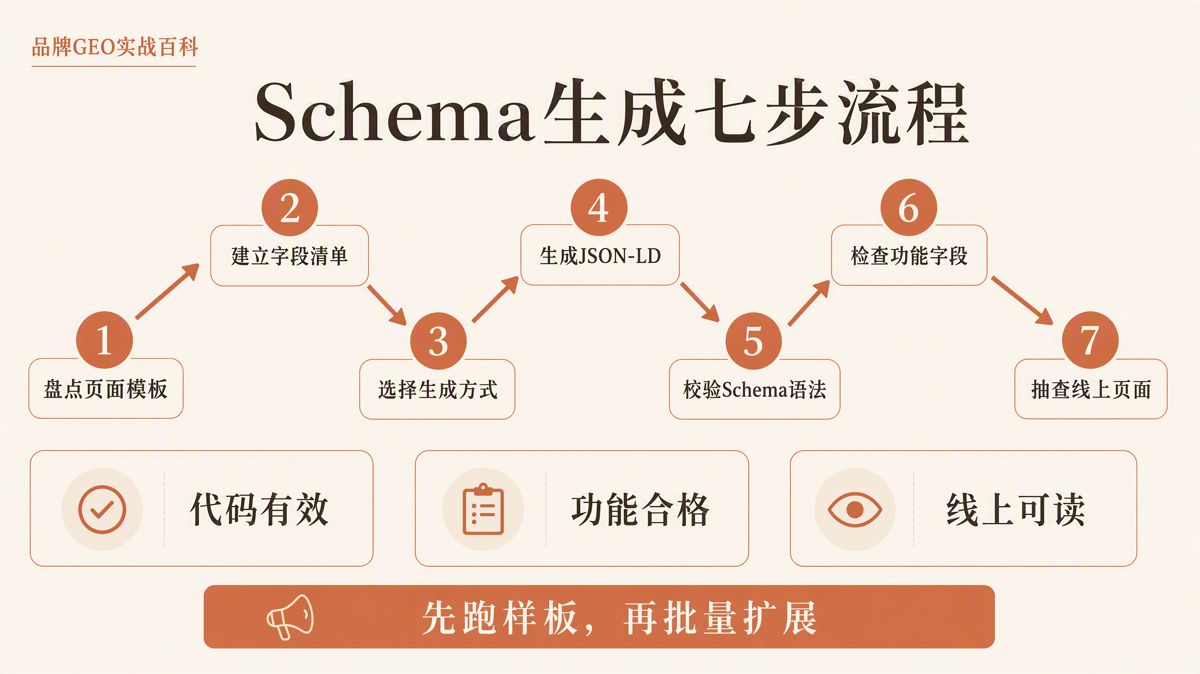
- Audit page templates: Map every distinct layout on your site to a primary Schema.org type.
- Build a field inventory: Confirm where each required value originates (on-page copy or synced CMS fields).
- Select your tooling: Match your workflow to your page volume (online generator, CMS extension, or programmatic pipeline).
- Generate JSON-LD: Review critical attributes, including
@type,@id, canonical URLs, dates, image assets, and entity references. - Clear syntax errors: Run the code through the Schema.org Markup Validator.
- Confirm feature compliance: Test against target search engine rich result tools.
- Deploy and audit live: Spot-check production URLs using live crawler inspection tools, archiving code records and test logs.
When rolling this out across a large site, start with a pilot cohort of 3 to 5 representative pages. Once those test pages pass all three validation stages, roll the template out sitewide.
This phased rollout helps you catch field discrepancies, missing data, and entity linking issues before they affect your entire index.
Frequently Asked Questions
Do I need to buy a paid Schema generator?
No. For a handful of pages, free online generators paired with official documentation and validators are sufficient. For large sites, costs stem from data mapping, template development, and testing pipelines, not from generating code.
Can a page contain multiple Schema types?
Yes. A single page can describe multiple related entities, provided you clearly define their relationships and ensure all structured fields reflect visible on-page content. Avoid adding irrelevant types or outputting conflicting duplicates.
Where should JSON-LD be placed in the HTML?
JSON-LD typically sits within a script tag in either the <head> or <body> section of the HTML document. Placement matters less than ensuring search engine crawlers can parse the script and that the data matches on-page content.
Why did my generator report no errors while the search feature test failed?
Syntax validators only check formatting, vocabulary validity, and data types. Search feature tests also verify whether the search engine supports that type, whether required properties are present, and whether the page meets specific search feature guidelines.
Do I need to regenerate Schema when page content changes?
Yes. Whenever titles, authors, dates, prices, stock status, images, or addresses change, your JSON-LD must update to match. Template-driven CMS setups handle this automatically; manual implementations require manual updates.
Does adding Schema guarantee citations by AI search engines?
No. Schema makes entities, attributes, and relationships explicit to machines, but whether generative AI systems crawl, understand, and cite your page depends on crawlability, content quality, source credibility, query relevance, and proprietary model policies.
Official Reference Links
The English edition is rewritten from the original Chinese article on the same topic.

Starbox AI is an AI marketing company based in Hangzhou, China. This article draws on Starbox project work. Please credit the source when quoting.
Related reading
 GEO Guide
Why AI Marketing Vendor Quotes Vary 10x: A 4-Step Vetting Checklist
Evaluate AI marketing proposals by delivery actions, not slide decks. Audit source infrastructure, fact cleaning, and clean-environment testing.
Oct 22, 2026 · 6 min read
 GEO Guide
Spotting GEO Scams: What Actually Drives AI Recommendations?
Automated AI ranking promises violate how LLMs work. Real AI recommendations rely on authoritative, structured facts across trusted public sources.
Oct 22, 2026 · 4 min read
 GEO Guide
How to Measure Your Brand's AI Visibility with a Spreadsheet
You do not need expensive software to track AI recommendations. A three-tier prompt framework and a simple spreadsheet can score your brand visibility in half a day.
Oct 21, 2026 · 6 min read