
Where Should You Publish Content to Get Cited by AI?
The short answer
Build an authoritative first-party fact page first, then distribute by query type. AI platforms offer no fixed lists or citation guarantees.
Key Facts
- On December 10, 2024, Product A announced live web search integration. The announcement noted that the system reads extensive web pages and extracts multiple keywords for parallel querying, but disclosed no preferred site list. Source: Product A official announcement.
- As of August 17, 2026, Product A's terms of service confirm only that it retrieves public internet information. The agreement clarifies that web search improves accuracy and timeliness, but cannot entirely prevent errors. Source: Product A terms of service.
- Product B's official help center states that its web search draws from over 100 verified, trusted sources. Publicly named categories include mainstream news, government notices, financial data platforms, and academic journals. Source: Product B official help center.
- Product B published 3 screening dimensions and 4 priority source categories. The 3 dimensions are relevance, authority, and timeliness. The 4 priority categories are government agency portals, authoritative media, academic journals, and official financial disclosures. Source: Product B official help center.
- Product B states that search-grounded answers include source links. Users can visit the original page to verify context; its developer service agreement notes that users must still independently verify third-party web content. Sources: Product B help center, platform service agreement.
- An audit of 6 official platform pages revealed zero definitive ranking guarantees. Neither product published a fixed whitelist of preferred websites, a domain authority tier list, a standardized indexing timeline, or an explicit citation guarantee. Source: Official documentation audit, August 17, 2026.
What Official AI Documentation Actually Discloses
Platform guidelines for web-connected AI models are far more conservative than many optimization playbooks claim.
Product A confirms a straightforward mechanism: when web search is enabled, the system retrieves publicly accessible internet information based on user prompts, then synthesizes an answer using those references. Early documentation noted that the system extracts multiple search keywords in parallel and parses large numbers of web pages.
Product B offers slightly more detail. Its web search spans over 100 verified sources, evaluating candidates across relevance, authority, and timeliness. It actively prioritizes government websites, authoritative news outlets, academic journals, and corporate earnings disclosures. Answers generated from web results include source links so users can inspect the underlying material.
Neither platform has published a list of "guaranteed citation sites," an official domain weighting scale, an indexing SLA, or a formula specifying how many published posts guarantee a citation.
Fixed partner directories, domain authority scores, unified indexing timelines, and citation guarantees do not exist in official documentation. They should never be treated as formal rules or sold to clients as guaranteed deliverables.
For clarity, this article uses "Product A" and "Product B" to represent two mainstream AI search products. These designations illustrate documented mechanisms and do not imply identical indexing, parsing, or ranking pipelines.
Why You Cannot Rely on a Single Platform or Community
First, search retrieval is determined by the user's specific prompt.
If someone asks when a company was founded, the AI looks for corporate sites, government registries, or established business reporting. If someone asks how to implement a specific API, technical documentation, academic papers, and developer forums carry more weight. If someone asks about a recent policy update, government portals and news reports are the most authoritative sources.
Whether your content gets retrieved depends primarily on how well it answers the active query, not the prestige of the platform hosting it.
Second, retrieval outputs are dynamic.
A slight variation in wording, a different query time, or changed conversational context can lead the AI to retrieve entirely different URLs. If a specific forum appears repeatedly in one testing session, that simply shows it performed well for those prompts at that moment. It does not prove the model has a permanent bias toward that forum.
A frequent mistake is confusing high visibility with an official algorithmic preference.
Popular communities host high volumes of discussion and index well, which makes them appear often during manual tests. Without official documentation confirming programmatic preference, these observations remain circumstantial. They are useful for prioritizing initial test channels, but they are not "official partner platforms."
Where Your First Piece of Content Belongs
Your primary piece of content belongs on an authoritative, long-term first-party page that you control.
For businesses, this usually means a public company website, a formal knowledge base, product documentation, a help center, or an open research report. Its purpose is to host raw facts, unify corporate positioning, and maintain an ongoing record of updates.
A complete first-party fact page should include six elements: - The full legal entity name - The exact date of the event or release - Explicit numeric definitions and baselines - Named primary data sources - Applicable operational scope or constraints - A clear changelog or update history
When discussing product features, specify exact version numbers and system requirements. When presenting case studies, state client authorization, sample sizes, and tracking methodologies. When citing regulations, link directly to the issuing government agency.
Keep these pages publicly readable. Do not hide core facts behind registration gates, embed critical data solely inside images, or force PDF downloads. Use clear, descriptive headings, answer the core question in the opening paragraph, and include units and timeframes in all data tables.
These are editorial and structural best practices, not guaranteed platform algorithms.
Publishing your source facts on your own domain creates a canonical reference point that you can update, revise, and verify indefinitely. External forums, press releases, and social posts can all link back to this single source of truth. While this does not guarantee an AI citation, it eliminates conflicting information across the web and gives human readers and AI retrieval systems an authoritative baseline.
Where to Publish Different Types of Content
Every channel should match the specific task of the content. The framework below illustrates how to divide content responsibilities without relying on speculative domain weights.
| Content Type | Primary Channel | Secondary Channel | Core Function | Required Evidence |
|---|---|---|---|---|
| Company & Product Facts | Official website, documentation, public reports | Trade publications, partner sites | Establish first-party source of truth | Dates, version numbers, entity names, source files |
| Regulations & Standards | Proprietary analysis citing the original text | Industry media, trade association portals | Bridge regulatory text with practical application | Document numbers, effective dates, scope |
| Technical Guides & Troubleshooting | Developer documentation, technical forums | Niche knowledge hubs, long-form columns | Solve practical technical issues | Environments, reproduction steps, error logs |
| Industry Analysis & Selection Criteria | Proprietary white papers, vertical publications | Professional Q&A forums, published transcripts | Explain analytical frameworks | Sample sizes, comparison matrices, constraints |
| Case Studies & Performance Data | Authorized client case study pages | Co-published client pages, industry media | Provide cross-verifiable business outcomes | Client sign-off, baselines, durations, metrics |
| Breaking Updates & Timely Notices | Official newsroom, verified social feeds | Curated summaries on the core fact page | Deliver time-sensitive information | Timestamps, source statements, subsequent corrections |
If your team has limited resources, prioritize three assets: a core fact page, an expert explanation, and an actionable Q&A post.
These cover three essential user intents: what the fact is, why it works, and how to execute it.
Relying solely on social updates leads to fast content decay. Relying solely on a static corporate website leaves specific user questions unanswered. Relying solely on third-party forums makes version control impossible. Each format serves a distinct purpose.
The "1 Core + 3 Contexts" Publishing Framework
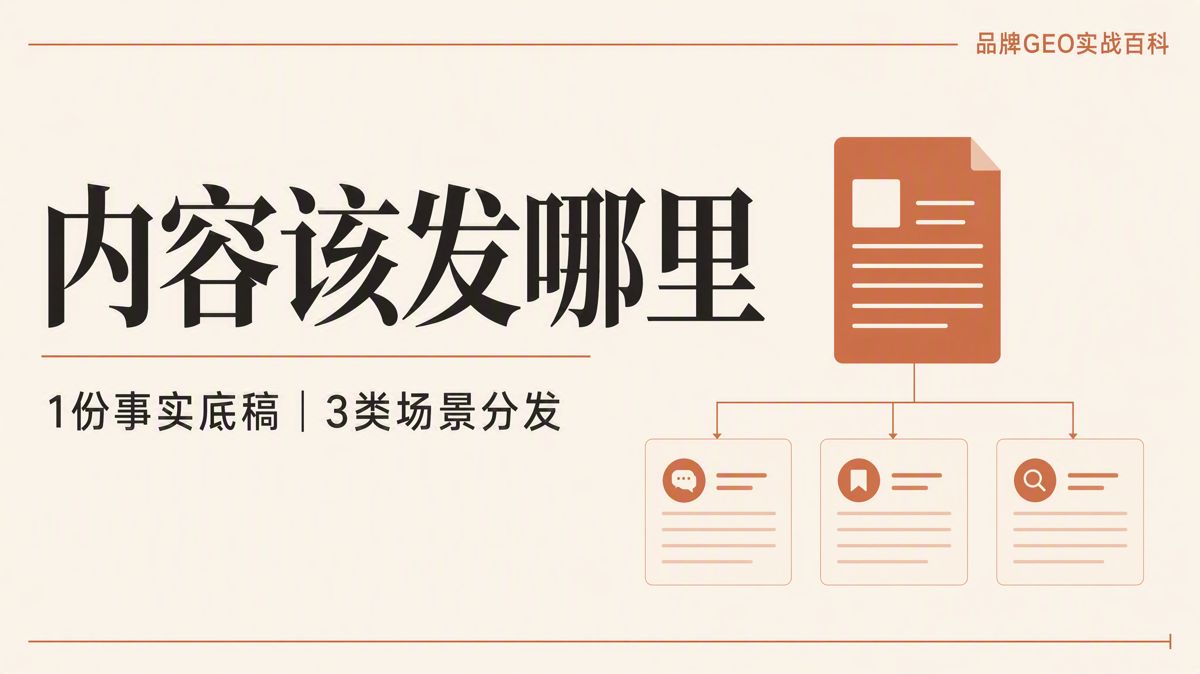
To scale content without burning out your team, organize each initiative around one primary fact sheet and three contextual adaptations.
Create a single, authoritative fact sheet that you can update indefinitely. Then, adapt those verified facts into an expert explanation, a targeted Q&A, and a short summary update. All four assets draw from the exact same dataset, but each answers a different search intent.
- The Primary Fact Sheet: Establishes entity names, dates, metrics, sources, and operational boundaries. Maintain a visible changelog. Before writing, compile all verifiable facts into a clean summary table to prevent discrepancies across channels.
- The Expert Explanation: Focuses on a high-frequency industry question, breaking down underlying causes, prerequisites, and criteria. Rather than copy-pasting the fact sheet, add actionable workflows and real-world examples relevant to the scenario.
- The Targeted Q&A: Solves one specific problem per post. Deliver the direct answer in the very first paragraph, followed by supporting evidence and boundary conditions. Target four clear query intents: what it is, why it matters, how to do it, and when not to use it.
- The Summary Update: Provides a brief notice of what changed and directs readers back to the primary fact sheet for complete context. Dynamic channels are great for alerts, but poor for hosting permanent records. When underlying facts change, update the core fact sheet first, then adjust downstream summaries.
This framework is not about spamming four different platforms. It is about packaging one verified reality into four distinct formats that match different retrieval prompts.
Whether an AI engine selects your content depends on real-time retrieval parameters. What your team can control is factual consistency, public crawlability, query coverage, and freshness.
Traditional SEO vs. Generative Engine Optimization (GEO)
Traditional SEO and Generative Engine Optimization (GEO) share foundational mechanics: pages must be publicly accessible, titles must align with content, claims require evidence, and search crawlers must be able to index the site.
The difference lies in the objective: traditional search focuses on ranking an entire URL to capture clicks, while Generative Engine Optimization focuses on helping an AI extract, understand, and cite a specific factual passage to answer a user's question.
| Dimension | Traditional SEO | Generative Engine Optimization (GEO) |
|---|---|---|
| Primary Goal | Page rank and organic click-throughs | Fact extraction and citation in AI answers |
| Content Unit | The complete web page | Self-contained paragraphs, tables, and Q&As |
| Key Signals | Keyword density, link equity, page performance | First-party facts, verifiable evidence, query fit, recency |
| Distribution | Build and optimize core landing pages | Core hub combined with multi-intent contextual assets |
| Validation | Keyword rankings, crawl rate, search impressions | Citation frequency for fixed prompts, source link appearance |
You do not need to discard your existing website. Focus on building out missing factual hubs, then expand coverage with expert guides and direct Q&A content.
If your team does not have a formal website yet, start with a publicly accessible, indexable documentation page. Ensure links remain permanent, the body text is crawlable without a login, and every revision is documented.
How to Validate Your Publishing Strategy
Do not wait for a mythical "indexing window." You can run an internal 30-day benchmark test, but keep in mind that tracking intervals (e.g., Day 0, 3, 7, 14, 30) are internal testing checkpoints, not official AI ingestion schedules.
Select 12 real user questions across four categories: entity facts, industry criteria, technical procedures, and recent developments (3 questions per category).
Test both products with web search enabled. Keep variables as consistent as possible: use the same user accounts, run queries at similar times of day, and test the exact same prompt phrasing. For every test, record three outcomes: - Did the AI incorporate your factual claims? - Did the answer include a clickable citation link? - What type of page was selected as the source?
Control your publishing variables across testing cycles: - Phase 1: Publish only the primary fact sheet. - Phase 2: Add the expert explanation. - Phase 3: Add the targeted Q&A content. - Phase 4: Add the short summary updates.
Do not overhaul titles, content, layout, and publishing times all at once. If you change multiple variables simultaneously, you will not know what influenced the result.
Evaluate citation visibility using a four-tier framework: - Tier 0: No relevant facts retrieved. - Tier 1: The engine uses your factual points, but cites no source URL. - Tier 2: The engine cites your specific URL. - Tier 3: Your URL is consistently cited across multiple prompts and testing intervals.
This four-tier scale is an internal operational benchmark, not an official platform rating.
At the end of 30 days, focus on two questions: Which page types appear most often for specific query categories? Which published facts were completely ignored?
The first answer tells you where to allocate future distribution resources. The second tells you where to revisit factual clarity, search-intent alignment, or page readability. A single citation is an isolated observation, not proof of an algorithmic rule.
Publishing Habits You Should Stop Immediately
- Identical cross-posting: Blasting the exact same article across ten third-party platforms creates content conflicts, duplicate data, and impossible version tracking. Different channels should answer different user intents, anchored by one single fact sheet.
- Fabricated third-party proof: Registering multiple accounts to post identical testimonials does not create independent authority. Case studies, credentials, awards, and media coverage must be publicly verifiable. Never package paid placements as independent reviews.
- Conclusions without boundaries: Publishing data without years, results without baselines, case studies without authorization, or policies without document identifiers makes it impossible for an AI system to evaluate your content as reliable reference material.
- Promising guaranteed indexing or citations: No platform has published fixed indexing timelines, domain-level ranking weights, or citation guarantees. Pitching guaranteed AI citations might sound compelling, but it will not hold up to testing and should never be used as a contractual deliverable.
FAQ
1. Can we publish only on professional Q&A communities?
We do not recommend relying on a single channel. Q&A platforms are great for answering specific questions, but core company facts, product versions, and case studies belong on a first-party page you maintain over the long term. Combining both creates a complete verification path.
2. Is an official company website guaranteed to be cited?
No. An official website is the best place to host first-party facts, but that does not guarantee an AI engine will use it. Crawlability, query match, supporting evidence, and freshness all influence the outcome. No platform guarantees citations.
3. Are authoritative media outlets always more effective than niche blogs?
Product B publicly states that it prioritizes categories like authoritative media, but it publishes no fixed domain weights. Whether an engine cites a specific piece depends on its relevance, freshness, and the verifiable evidence within the text.
4. How soon after publishing should we test citations?
You can track results at intervals like day 0, 3, 7, 14, and 30, but treat these strictly as internal checkpoints. Neither platform has published an indexing timeline, so these intervals are not official platform rules.
5. Should we syndicate the exact same article across multiple platforms?
We do not recommend copy-pasting identical text. Keep the underlying facts consistent, but adapt them into in-depth explanations, targeted Q&As, technical guides, or short updates. That prevents maintenance issues while addressing different user intents. Keep all numbers, dates, and scopes aligned.
6. Can we execute an AI citation strategy without an official website?
Yes. You can start with publicly accessible documentation hubs, professional community columns, or industry publications, as long as you clearly document company entity details, sources, and revision histories. Once resources allow, centralize first-party facts on your own domain.
7. What is the difference between being mentioned and being cited?
If an AI response includes your company or product name, that is only a brand mention. A citation occurs when the response provides a clickable source link that leads back to your original page. Your tracking logs should record these two outcomes separately.
8. Can an agency guarantee AI citations to a client?
No. Official user agreements explicitly state that outputs may be inaccurate, results change over time, and third-party content must be verified by the user. Commercial commitments should focus on deliverable content, testing volume, and audit rigor, never guaranteed citations.
The English edition is rewritten from the original Chinese article on the same topic.

Starbox AI is an AI marketing company based in Hangzhou, China. This article draws on Starbox project work. Please credit the source when quoting.
Related reading
 GEO Guide
Why AI Marketing Vendor Quotes Vary 10x: A 4-Step Vetting Checklist
Evaluate AI marketing proposals by delivery actions, not slide decks. Audit source infrastructure, fact cleaning, and clean-environment testing.
Oct 22, 2026 · 6 min read
 GEO Guide
Spotting GEO Scams: What Actually Drives AI Recommendations?
Automated AI ranking promises violate how LLMs work. Real AI recommendations rely on authoritative, structured facts across trusted public sources.
Oct 22, 2026 · 4 min read
 GEO Guide
How to Measure Your Brand's AI Visibility with a Spreadsheet
You do not need expensive software to track AI recommendations. A three-tier prompt framework and a simple spreadsheet can score your brand visibility in half a day.
Oct 21, 2026 · 6 min read