
GEO for SPAs: Put Your Real Content in the Initial HTML
The short answer
AI crawlers cannot be trusted to run JavaScript. For generative engine optimization on an SPA, your server's initial HTML response must contain the factual text.
Generative Engine Optimization (GEO) focuses on whether your content can be discovered, parsed, and understood by generative AI systems. The crawlers dispatched by these platforms are automated programs that scan web pages to retrieve information. Evaluating whether your website is readable to an AI crawler requires more than simply checking how it looks in a desktop browser.
If your site runs on a Single-Page Application (SPA) architecture, you must inspect the very first payload returned by your server. SPAs typically deliver a bare-bones HTML shell and rely on client-side JavaScript to fetch data and render product descriptions, service lists, case studies, FAQs, and article copy.
This setup often creates a false sense of security. A developer opens the page in Chrome, sees full text and rich media, and assumes an AI crawler sees the same thing. In reality, the user sees a page after scripts have run. A crawler making a direct HTTP request may receive nothing more than an empty root container and a couple of script tags.
The critical asset to inspect is the initial HTML: the raw code returned on the first request before any client-side script execution.
Before debating whether React, Vue, or another framework is superior, answer one technical question:
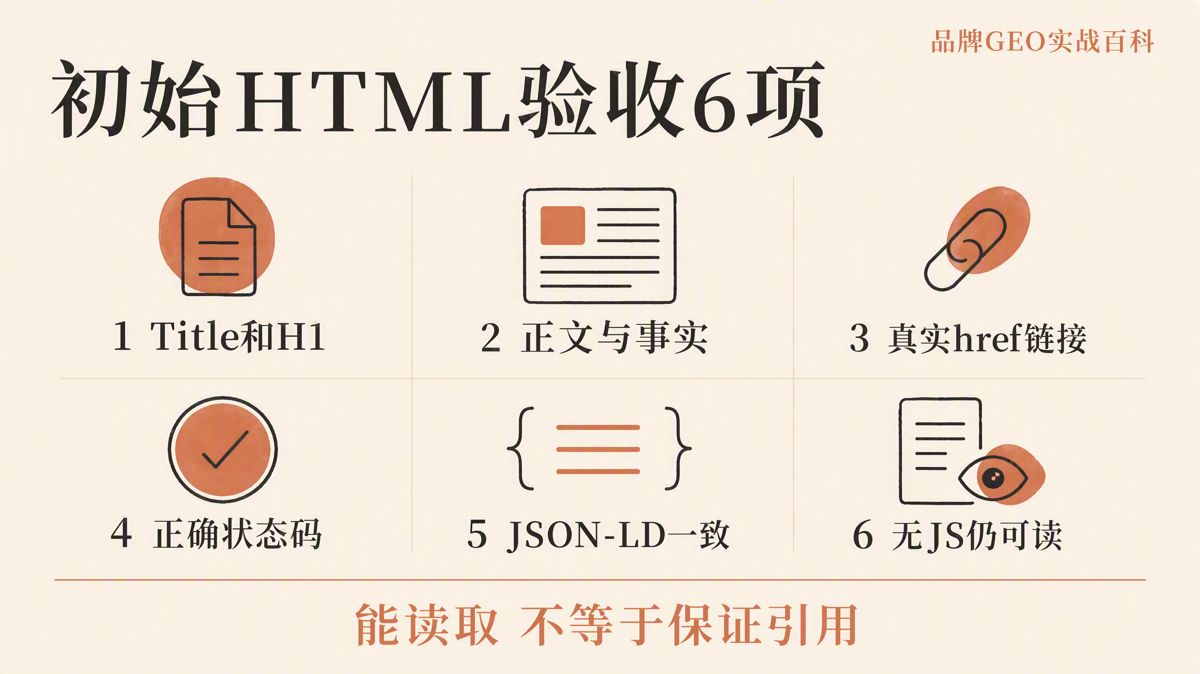
Does the initial HTML returned by your server contain the page title, the H1 tag, the main body text, primary navigational links, and structured data?
JavaScript should handle filtering, modal dialogs, forms, and client-side interactions. It should not be responsible for generating the core factual record of your business.
Do Not Assume Every Crawler Runs JavaScript
It is a mistake to assume AI crawlers never run JavaScript, but it is an equal mistake to assume they all do.
In traditional SEO, Google states in its official documentation that Googlebot queues pages for rendering and executes JavaScript using a headless Chromium browser. Even so, Google explicitly notes that not all web crawlers execute JavaScript, recommending server-side rendering or pre-rendering as a safer baseline.
Documentation from OpenAI and Anthropic details crawler user-agents, IP ranges, and robots.txt compliance. Neither platform guarantees that its crawlers will execute client-side scripts like a complete browser or wait for asynchronous hydration before scraping content.
Relying on guesswork is poor engineering. A reliable standard is straightforward:
The initial HTML of critical public pages must directly include the page title, H1, body copy, key links, and structured data. A crawler should be able to extract your core factual content without executing a single line of JavaScript.
First Step: Inspect the Raw Response, Not the Rendered DOM
A typical client-rendered SPA returns an initial response like this:
<div id="app"></div>
<script src="/assets/app.js"></script>
Product details, pricing, FAQs, and case studies only appear after the script loads, fires an API call, and modifies the DOM.
Human visitors rarely notice the delay. But an automated crawler that lacks a full browser rendering engine—or one that sets a short timeout on page execution—reads only an empty container.
Do not rely on the Elements panel in your browser's Developer Tools for this check. That panel shows the rendered DOM after script execution, not the raw HTML sent by the server.
Run three checks before deployment:
- View the raw page source in your browser (
view-source:URL) to see the server's immediate output. - Request the URL via the command line and save the raw response.
- Disable JavaScript in your browser settings and reload the page.
You can inspect the raw response using curl:
curl -L https://example.com/product/alpha -o page.html
Open page.html and search for your product name, the H1 heading, core technical specifications, and the first paragraph of copy.
If those elements are missing from the raw file, the page does not meet the basic threshold for initial HTML readability, regardless of how complete it looks in a browser.
| Raw HTML Inspection Result | Evaluation | Recommended Action |
|---|---|---|
| Contains Title, H1, body copy, key links, and core facts | Pass | Maintain setup; verify HTTP status codes and content parity |
| Contains only a summary; full body copy relies on JS | At Risk | Migrate critical routes to SSG, SSR, or route pre-rendering |
| Contains only a root node and script tags | Fail | Fix rendering architecture before spending time on copy optimization |
You Don't Have to Rebuild Everything: Pick the Right Rendering Method per Route
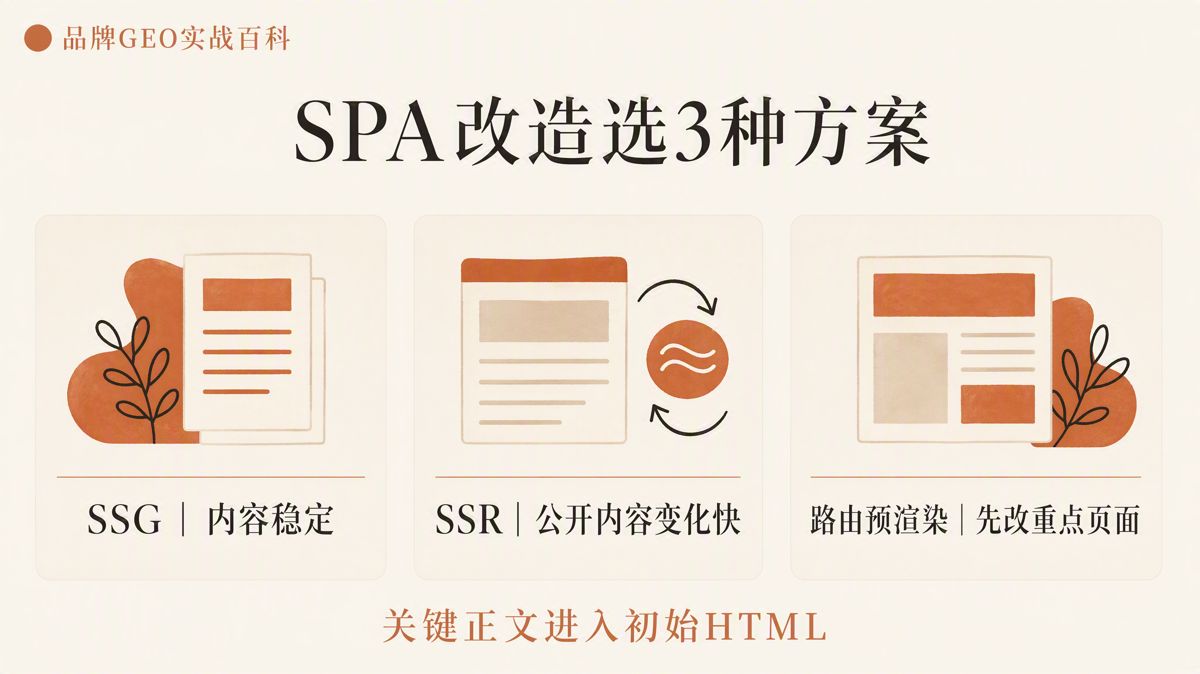
If your initial HTML lacks substantive body text, you do not necessarily need to scrap your existing SPA. Depending on your update frequency, total URL count, and technical stack, you can adopt Static Site Generation (SSG), Server-Side Rendering (SSR), or route-based pre-rendering.
Every product, service, and article should have a distinct, directly accessible URL.
SSG: Generate Full HTML at Build Time
Static Site Generation pre-builds complete HTML pages for each public URL during your deployment build process. When a user or crawler requests a URL, the server delivers a static file immediately.
Next.js documentation highlights that SSG compiles HTML at build time, allowing pages to be cached and served globally via a Content Delivery Network (CDN).
SSG works well for:
- Product overviews, service descriptions, about pages, and case studies.
- Documentation, knowledge bases, and help center articles.
- Content managed via a CMS that updates on a publishing schedule rather than per-second.
- Sites where public URLs can be defined during the build step.
- Setups requiring fast, consistent HTML delivery at scale.
The trade-off: updating copy requires a site rebuild or an incremental static regeneration (ISR) pipeline. Authenticated dashboards and private user portals should remain client-rendered behind logins.
SSR: Generate HTML on Every Request
Server-Side Rendering computes the HTML on the server each time a request hits the application, pulling the freshest data before sending the payload.
SSR works well for:
- Public pages with fast-changing data, such as real-time pricing or inventory availability.
- Dynamic listings that must reflect backend state immediately without exposing private user data.
- Applications where the server infrastructure can reliably support compute-on-demand.
SSR introduces operational considerations, including server resource usage, caching layers, database timeouts, and fallback handling.
If an upstream API times out or throws an error, an SSR server might return an empty body alongside a 200 OK status code. When adopting SSR, ensure you have robust error handling, caching, and accurate HTTP status reporting in place.
Route-Based Pre-rendering: Target High-Value Pages First
If a complete migration to SSR or SSG is not immediately feasible, generate static HTML snapshots for your most important public URLs.
Prioritize:
- The homepage.
- Core product and solution pages.
- Primary service offerings.
- Company overview and brand background.
- High-performing case studies.
- High-traffic editorial and informational content.
This serves as a practical stepping stone: deliver complete initial HTML on high-value assets today, then plan a wider architectural migration over time.
Note that returning pre-rendered static HTML exclusively to bots while serving an empty SPA to users—dynamic rendering—is considered a workaround by Google and is not recommended as a permanent setup. Ensure that the core factual content remains identical for both bots and users.
| Rendering Approach | When HTML Is Generated | Best Suited For | Main Trade-offs |
|---|---|---|---|
| SSG (Static Site Generation) | At build time | Stable pages: products, services, articles, case studies | Requires builds or revalidation routines for updates |
| SSR (Server-Side Rendering) | On every incoming request | Rapidly changing public information | Server compute overhead, caching, and error resilience |
| Route Pre-rendering | At release or via scheduled jobs | High-priority URLs on legacy SPAs | Snapshot maintenance and parity monitoring |
Initial HTML with Full Copy Does Not Mean Sacrificing SPA Interactivity
Moving to server-rendered or static HTML does not mean stripping away client-side features like search filters, interactive calculators, carousels, forms, or authenticated sessions.
In modern frameworks, the server delivers complete HTML, and JavaScript subsequently binds to the DOM to enable dynamic behavior. This process is known as hydration.
Split your page components into two categories:
- Factual Content: Brand positioning, product specifications, service scope, case evidence, FAQs, author details, and publication dates. These must live in the initial HTML.
- Interactive Logic: Filter dropdowns, sort toggles, modals, personalized views, and authenticated states. These can be handled by client-side JavaScript.
Private, authenticated data should never be pushed into public server-rendered HTML merely for search visibility.
6 Technical Fundamentals to Check Alongside the HTML
Getting your body copy into the initial HTML solves the most urgent crawling bottleneck. However, discovery and indexing also depend on six supporting technical elements.
1. Give Every Page a Unique, Stable URL
Products, services, and articles need unique, permanent URLs. Avoid routing based on hash fragments (such as example.com/#/product/1).
Use the browser History API to manage routing and link internal pages using standard anchor tags with valid href attributes. This ensures each page can be crawled, shared, and indexed independently.
2. Return Accurate HTTP Status Codes
Your server must return true status codes: 200 OK for valid pages, 404 Not Found for non-existent routes, and appropriate 3xx codes for redirects.
A common SPA anti-pattern is returning a 200 OK with an empty root shell for every incoming path, forcing client-side code to handle 404 views. This causes crawlers to perceive broken or non-existent URLs as valid pages.
3. Update Head Tags per URL
Every public URL must render its own metadata directly in the initial HTML:
- A unique
<title>tag. - A descriptive
<meta name="description">. - A
<link rel="canonical">tag pointing to the preferred URL. - Appropriate robots meta tags.
Do not wait for client-side scripts to overwrite generic default tags after the page loads.
4. Align Structured Data with On-Page Copy
Structured data should be embedded directly in the initial HTML using JSON-LD.
The entities declared in your schema—such as brand names, pricing, authors, dates, and FAQ blocks—must match the visible text on the page. Schema markup supports parsing; it does not replace visible content, nor does it guarantee citations.
5. Use Crawlable Anchor Links
Connect your internal architecture using valid HTML links: <a href="/target-page">.
If internal navigation relies entirely on JavaScript click handlers (onClick) without an underlying href, crawlers may fail to discover deeper pages on your site.
6. Make Server-Side Data Fetching Resilient
When rendering on the server, backend API failures must not produce an empty page paired with a 200 OK. Implement caching fallbacks, default rendering states, and clear error response codes to prevent crawlers from indexing empty responses during transient API outages.
An 8-Step Implementation Sequence
Step 1: Inventory All Public URLs
Export every public URL across your site and categorize them: homepage, products, services, articles, case studies, and utility pages.
Step 2: Audit Raw HTML Across Categories
Check each category using curl or page-source inspection. Confirm whether the <title>, H1, opening copy, core facts, anchor links, and JSON-LD are present in the raw payload.
Do not test a single page and assume the entire site functions the same way; different routes often use different data loading strategies.
Step 3: Prioritize Routes for Migration
Avoid attempting a total frontend rewrite in one sprint. Begin with the homepage, core product pages, primary services, and highest-traffic content.
Step 4: Assign the Right Rendering Model
- For stable public content: apply SSG.
- For frequently updated public data: apply SSR.
- For legacy routes that cannot be immediately rebuilt: apply route-level pre-rendering.
Step 5: Inject Core Information into Initial HTML
Ensure the page title, H1, body copy, canonical tags, JSON-LD, and internal links render from the server, while preserving client-side interactivity.
Step 6: Verify Content Parity Across Three Views
In your staging environment, compare: 1. The raw HTML returned by the server. 2. The rendered DOM after script execution. 3. The visual presentation seen by the user.
Core facts must remain consistent across all three.
Step 7: Inspect Server Logs Post-Launch
Review your server access logs to confirm that platform crawlers are visiting your URLs, receiving 200 OK status codes, and fetching full payloads. Validate crawler identities using reverse DNS or officially published IP ranges rather than relying on User-Agent strings alone.
Step 8: Track Retrieval and Citation
Archive pre- and post-migration page versions and release dates. Monitor whether your updated pages appear in search indexes, receive direct crawler traffic, and get cited in relevant generative AI outputs.
Technical Launch Checklist
- Every critical page has an independent, stable URL.
- Direct HTTP requests return a
200 OKwith full body text in the initial response. - The raw HTML contains the
<title>, H1, introductory copy, and core factual details. - Internal navigation uses native
<a href="...">elements. - Non-existent routes return a true
404 Not Foundstatus code. - Canonical links reference the correct, preferred URL.
- JSON-LD structured data matches the visible text on the page.
- Core content remains readable with JavaScript disabled.
- Interactive components (forms, filters, modals) function properly after hydration.
- No factual contradictions exist between the raw HTML and the client-rendered DOM.
robots.txtdoes not block access to critical public pages or necessary assets.- Server logs confirm successful crawler visits and proper response delivery.
Readability Is the Prerequisite, Not a Citation Guarantee
The primary technical consideration for an SPA in GEO is simple: does your server deliver the real text on the first response?
Rather than guessing how advanced an AI bot's JavaScript engine might be, establish an unambiguous engineering baseline: deliver complete facts in the initial HTML, and let JavaScript handle user interactions.
Use SSG for stable resources, SSR for dynamic data, and route-based pre-rendering for transitional fixes.
Solving initial HTML delivery ensures your content is readable. Whether an AI system subsequently indexes, retains, or cites that content depends on content quality, domain authority, factual credibility, and the retrieval strategies of each generative platform. But if the crawler cannot read your text on the first request, none of those downstream factors matter.
FAQ
1. Do all AI crawlers refuse to run JavaScript?
Not necessarily.
Googlebot executes JavaScript using a headless Chromium browser in its rendering queue. However, documentation from OpenAI and Anthropic makes no commitment to execute scripts like a full browser.
Engineering audits should verify that core text is available in the initial HTML rather than assuming bots will run scripts.
2. Do you have to rewrite the entire SPA from scratch?
No.
You can start with priority public routes—such as the homepage, core product pages, service offerings, and high-value case studies—using SSG, SSR, or pre-rendering, and expand from there.
3. How do you choose between SSG and SSR?
Choose SSG for relatively static content that changes only on publication. Choose SSR when public content must reflect real-time changes on every request.
Both deliver full HTML on the initial response; they differ in build timing, caching strategies, and server overhead.
4. Can you return static HTML only to bots and keep the SPA for users?
Google considers dynamic rendering a temporary workaround and advises against relying on it long-term.
The core facts seen by bots and human users must match. A better path is SSR or SSG with client-side hydration.
5. Does switching to SSR guarantee that AI models will cite your pages?
No.
SSR only solves content readability. Whether an AI system indexes or cites your content depends on access permissions, source authority, information quality, factual density, and platform-specific retrieval mechanisms.
6. How do you prove that the technical fix worked?
Fetch the raw server response using tools like curl to confirm that titles, H1 tags, body paragraphs, and links exist in the initial payload. Then verify status codes, inspect the page with JavaScript disabled, check structured data alignment, and monitor server logs for bot access.
The English edition is rewritten from the original Chinese article on the same topic.

Starbox AI is an AI marketing company based in Hangzhou, China. This article draws on Starbox project work. Please credit the source when quoting.
Related reading
 GEO Guide
Why AI Marketing Vendor Quotes Vary 10x: A 4-Step Vetting Checklist
Evaluate AI marketing proposals by delivery actions, not slide decks. Audit source infrastructure, fact cleaning, and clean-environment testing.
Oct 22, 2026 · 6 min read
 GEO Guide
Spotting GEO Scams: What Actually Drives AI Recommendations?
Automated AI ranking promises violate how LLMs work. Real AI recommendations rely on authoritative, structured facts across trusted public sources.
Oct 22, 2026 · 4 min read
 GEO Guide
How to Measure Your Brand's AI Visibility with a Spreadsheet
You do not need expensive software to track AI recommendations. A three-tier prompt framework and a simple spreadsheet can score your brand visibility in half a day.
Oct 21, 2026 · 6 min read