
Don't Rely on a GEO Score: An 11-Item Pre-Launch Checklist
The short answer
Rolling AI visibility into one composite score hides critical issues. Use this 11-item pre-launch checklist to monitor, diagnose, and iterate GEO performance.
Generative Engine Optimization (GEO) focuses on whether brand content can be discovered, understood, cited, and recommended by generative AI engines.
If your brand appears in an AI response, does that mean your GEO strategy succeeded? Not necessarily.
An engine might mention your brand name without citing your website as a source. It might cite your link, but the linked page might not actually support the answer. Or, an AI prompt might drive a visitor to your site who immediately bounces without taking action.
GEO monitoring cannot be reduced to a binary "did we show up?" check, nor can it be compressed into a single composite score. You need to systematically track your target entity—a brand, organization, executive, or product—across whether it appeared, how it appeared, what sources were cited, and whether it drove downstream business actions.
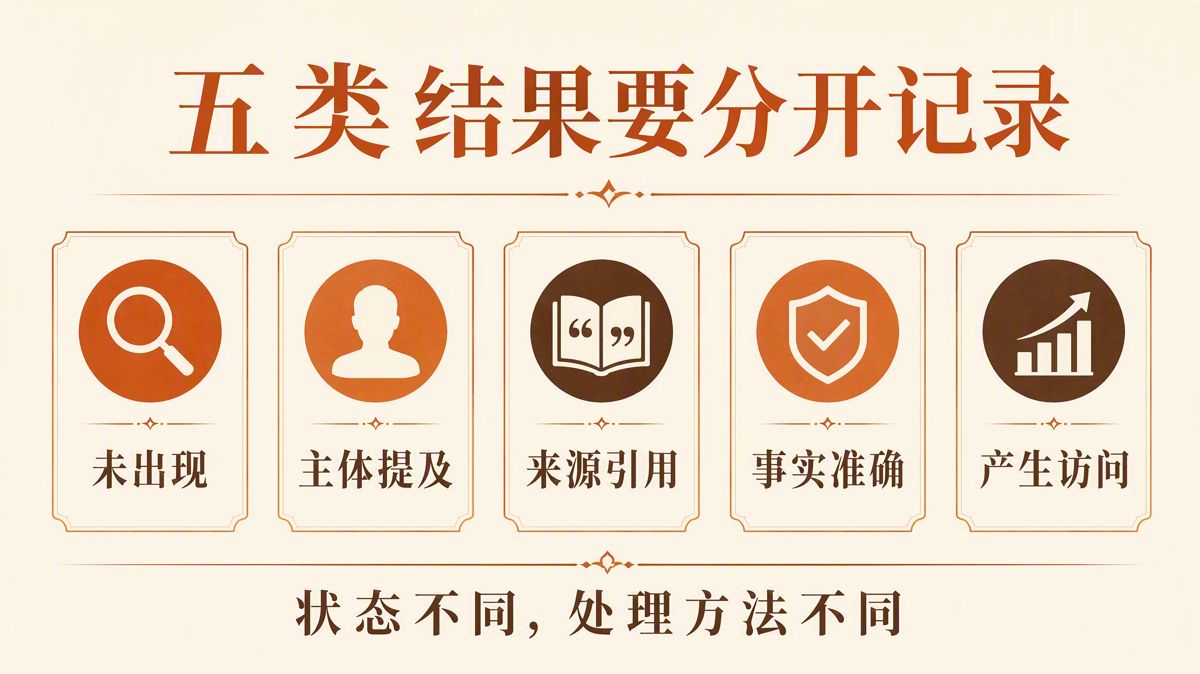
Every query result falls into one of five states:
- Not present: The entity does not appear in the answer or sources.
- Entity mention: The brand is named in the response, but no source link is provided.
- Source citation: A specific URL is cited in the reference area.
- Factual accuracy: Brand names, specifications, relationships, and product boundaries are accurately stated.
- Downstream action: The appearance generates identifiable site traffic or conversion behavior.
Each state demands a different operational response:
- If you do not appear: Verify whether the page is indexed, expand prompt coverage, or resolve topical content gaps.
- If you appear with factual errors: Correct product specifications, entity relationships, pricing terms, or operational constraints.
- If a source link is displayed: Verify that the URL is live and that the on-page text directly backs up the AI response.
- If traffic arrives without conversions: Audit the landing page experience and the subsequent conversion path.
The goal of monitoring is not to generate a vanity score to declare victory. It is to trace every anomaly back to a specific audit, correction, and re-test workflow.
Understand the Three Primary Data Sources First
Google, Bing, and OpenAI provide data covering different stages of retrieval and generation. Merging them into a single score obscures what is actually happening.
The Google AI Overviews and Search optimization guide recommends using the Generative AI performance report in Google Search Console to monitor how content performs within Google's generative search experiences. Google notes that third-party tools cannot access Google's internal ranking or AI systems, cautioning against tools claiming proprietary access to these metrics.
Bing Webmaster Tools provides a Search Performance report that surfaces clicks, impressions, CTR, crawl requests, crawl errors, and indexed pages across both standard web search and conversational chat.
OpenAI's Publishers and Developers FAQ explains that referral URLs from ChatGPT search results automatically append the parameter utm_source=chatgpt.com. Analytics platforms can use this tag to identify referral traffic originating from ChatGPT.
In short: Google provides data on how your content performs in its generative search features; Bing tracks crawl health, impressions, and conversational chat visibility; and OpenAI provides referral parameters to identify downstream visits from ChatGPT.
These sources should cross-reference one another, but they cannot be treated as interchangeable metrics.
Before launching a monitoring program, audit your setup against these 11 checkpoints:
| No. | Checkpoint | Target State | Common Mistake |
|---|---|---|---|
| 1 | Target Questions | Every query maps to a clear commercial intent | Only testing branded queries |
| 2 | Prompt Versioning | Phrasing, qualifiers, and language are fixed | Modifying the prompt on each run |
| 3 | Test Parameters | Engine, timestamp, region, and account status are recorded | Mixing test environments |
| 4 | Baseline Data | Pre-optimization benchmarks are complete and documented | Beginning tracking only after publishing content |
| 5 | State Separation | Mentions, citations, and accuracy are tracked as separate columns | Using an aggregate score instead of raw signals |
| 6 | Source Verification | Cited URLs load properly and support the generated claims | Saving answer screenshots without checking sources |
| 7 | Downstream Tracking | Referrals, landing pages, and conversions are tracked | Relying exclusively on AI answer screenshots |
| 8 | Root-Cause Attribution | Issues are traced to indexing, content, proof, or conversion | Rewriting entire pages whenever visibility drops |
| 9 | Single-Variable Changes | Each round tests one explicit hypothesis | Changing multiple elements at once |
| 10 | Controlled Re-testing | Pre- and post-change tests run under identical conditions | Comparing numbers across altered queries |
| 11 | Version Changelog | Edits, owners, and re-test dates are fully logged | Inability to identify why an AI response changed |
1. Align Target Questions with Commercial Intent
Your prompt set should not stop at "Who is Brand X?" or "What does Product Y do?" You must monitor the questions buyers ask across every evaluation phase: category research, vendor comparisons, use-case fit, risk mitigation, pricing structures, case studies, and implementation requirements.
Every prompt in your test bank should have a declared business purpose: Are you checking for basic entity discovery? Shortlist inclusion? Source citations? Or referral click-throughs?
Do not overload a single prompt with multiple evaluation goals. For example, "Which vendor is best for X?" helps you observe recommendation rankings, but it does not prove purchase readiness. Assigning a clear business intent to each query makes it possible to evaluate whether visibility shifts actually matter to the pipeline.
2. Lock Down Fixed Query Versions
Changing a single modifier can completely shift an AI engine's retrieval path. Adding phrases like "enterprise-grade," "for mid-market teams," "on-premise deployment," or "best value" alters both information retrieval and synthesis.
Record the exact sentence structure, language, qualifiers, and version ID for every test query. Never log a prompt as a vague topical tag.
When you want to explore new variations, create a new prompt version rather than overwriting the old one. This preserves a controlled baseline for longitudinal comparison while letting you test emerging query patterns.
3. Log Test Parameters Thoroughly
Every test run must document:
- Platform, model, or interface entry point
- Timestamp
- Geographic location/IP
- Language settings
- Login and account tier
- Web-browsing toggle status
If results are influenced by account history or personalization, document those account parameters. When variables cannot be controlled, list them explicitly as testing constraints rather than assuming consistent query environments.
Screenshots must capture the prompt, the complete generated text, the reference/source module, and the timestamp. Capturing only the text snippet prevents you from verifying the platform entry point or confirming source link changes later.
4. Establish a Pre-Optimization Baseline
A baseline records the exact state of your visibility before making content updates. It must document your current entity presence, mention types, cited URLs, factual errors, indexation status across major engines, and existing referral visits for your prompt bank.
Without an established baseline, noting that your brand "appeared" after an update tells you what happened today, but proves nothing about what caused the change.
Baselines do not require positive data. A zero, an unindexed status, or a missing mention is valuable data. Record these states as "0" or "Not Observed"—never leave cells blank or reconstruct historical numbers from memory.
5. Track Different Outcomes Separately
Classify every query result across these five distinct states:
| State | What to Record | What It Does NOT Prove |
|---|---|---|
| Not Present | Entity absent from both answer and citations | That the page is unindexed by search engines |
| Entity Mention | Brand named in text without source links | That the official site is being used as a source |
| Source Citation | Website URL appears in citations | That the page copy supports every claim made |
| Factual Accuracy | Names, specs, terms, and constraints are correct | That accurate facts will generate clicks or leads |
| Traffic Generated | Analytics confirms referral session and landing page | That the session will yield a qualified conversion |
These states can appear independently.
An engine might cite your documentation while repeating an outdated product specification. Or it might describe your service accurately without providing a link back to your domain. Separating these signals allows you to determine whether your next sprint needs factual corrections, stronger corroborating evidence, technical link adjustments, or landing page optimization.
6. Audit Every Cited Source Manually
When an AI engine includes a link to your domain, open it and verify:
- Does the URL return a 200 OK status?
- Is the page publicly accessible without authentication barriers?
- Is the publication or update date current?
- Does the body text explicitly corroborate the AI engine's claim?
- Does the link point to original source material or syndicated copy?
- Are the product names and version numbers aligned with the generated text?
If an authoritative page was updated but the engine still serves stale specifications, log the current source value, the generated value, the exact discrepancy, and the date observed.
A citation badge merely indicates the engine surfaced a link; it does not guarantee the facts were validated.
7. Cross-Reference AI Output with Analytics Data
A screenshot confirms what the AI answered; webmaster tools and web analytics confirm whether pages were discovered, displayed, clicked, and browsed.
Store these two datasets separately, then reconcile them by date, URL, and traffic source:
- Review Google Search Console generative AI performance reports and crawl data.
- Check Bing Webmaster Tools for both standard search and conversational chat impressions, crawl stats, and indexation rates.
- Isolate ChatGPT referrals using
utm_source=chatgpt.com.
Keep in mind that AI sessions without referrer tags may be bucketed under direct traffic. As a result, identifiable referrals represent a baseline, not a comprehensive total. Document untracked traffic as an analytics limitation instead of inflating your figures with unverified estimates.
8. Pinpoint Where Breakdowns Occur
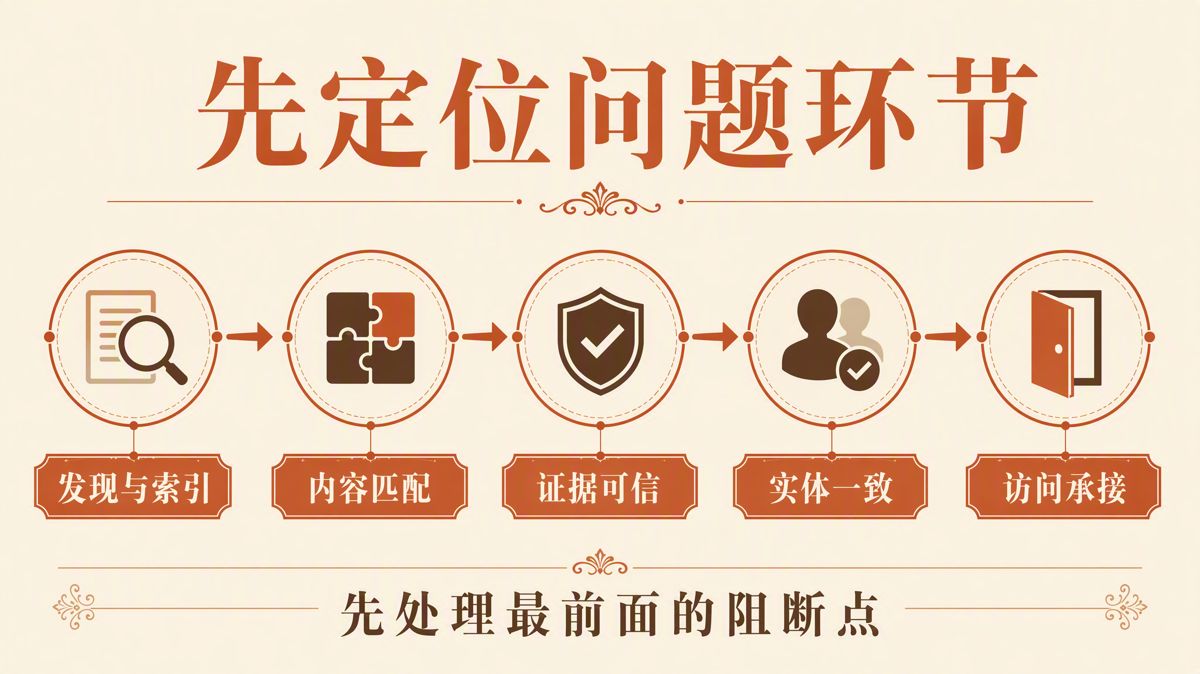
When visibility drops or fails to materialize, identify the exact breakdown stage before editing any content:
| Problem Area | Typical Symptom | Priority Check |
|---|---|---|
| Discovery & Indexing | Page missing from search results or showing crawl errors | Server permissions, internal linking, XML sitemaps, indexation status |
| Query Matching | Page is indexed but consistently fails to appear for relevant queries | Search intent coverage, H2/H3 structure, direct answer blocks, content depth |
| Source Authority | Entity is mentioned, but citations are weak or overridden by third parties | Original citations, author attribution, publication dates, third-party validation |
| Entity Consistency | Inaccurate corporate details, legacy pricing, or confused product lines | Structured data schema, legacy page cleanup, cross-platform brand data |
| Downstream Conversion | Traffic arrives from AI referrals but produces zero interactions | Message match on landing page, call-to-action visibility, forms, mobile UX |
A single issue can span multiple stages, but you should always resolve the earliest breakdown point first. Rewriting body copy will not help if the page cannot be crawled.
9. Tie Every Edit to a Single Hypothesis
If you change the page title, rewrite the body copy, modify schema markup, publish external press releases, and change the URL slug at the same time, you cannot determine what drove any subsequent shift in AI output.
Structured data—machine-readable code that helps search engines parse page entities—functions as an independent variable alongside titles and body copy.
For every iteration, document:
- The exact element changed
- The pre-change state
- The post-change state
- The rationale or evidence backing the change
- The expected outcome
Testing a single hypothesis does not mean changing only one word. It means all changes within an iteration must serve the same testable question.
For instance, updating a section heading and its accompanying paragraph to clarify enterprise deployment constraints tests one coherent hypothesis. However, updating that paragraph while simultaneously changing your domain name and pruning old case studies introduces competing variables that muddy the analysis.
10. Maintain Strict Re-Testing Controls
Re-testing must use identical prompt versions, language settings, and engine parameters, alongside logged timestamps.
AI systems update continuously. A variation in results indicates only that the output changed under those recorded parameters; it does not prove your edit was the sole cause.
You can run exploratory queries alongside fixed benchmarks, but manage them in separate tracks:
- Benchmark sample: Fixed prompts used to track changes over time.
- Exploratory sample: Dynamic prompts used to uncover emerging user phrasing.
Blending these two data sets distorts historical performance trends.
11. Maintain a Versioned Audit Ledger
A structured changelog is essential for tracking optimization efforts. Your ledger should capture:
- Query ID
- Target URL
- Summary of changes
- Supporting documentation/source links
- Task owner
- Deployment timestamp
- First re-test date
- Re-test outcome
- Recommended next steps
If content is rolled back, redirected, or if supporting proof becomes obsolete, log that history.
When data shifts unexpectedly, review your ledger, page indexation, and platform update logs before reverting code. Without a changelog, teams often repeat past mistakes or mistake an engine-wide algorithm update for an on-page content failure.
Use a Traffic Light System to Direct Iteration
Once you audit your program against the 11 checkpoints, use a simple Red, Yellow, Green status to decide if you are ready to iterate:
| Status | Audit Result | Action Required |
|---|---|---|
| Red | Missing baselines, inconsistent prompt versions, unverified sources, or unresolved factual errors | Pause reporting and refrain from drawing optimization conclusions |
| Yellow | Data logged, but missing testing parameters, vague issue attribution, or too many concurrent variables | Backfill missing parameters and run clean verification tests |
| Green | Queries, conditions, baselines, states, sources, edits, and changelogs are fully verifiable | Proceed with the next optimization sprint |
This framework does not rate your AI visibility—it evaluates whether your monitoring data is dependable enough to inform business decisions.
Stop at Red. Fix the gaps at Yellow. Move forward only when your process is Green.
Executing these 11 checkpoints will not guarantee that an AI engine never changes its answers, nor will it guarantee instant citations. What it does provide is operational clarity: when an answer shifts, you will know precisely what broke, what to adjust, and how to validate the fix.
Frequently Asked Questions
Is testing branded queries enough?
No. Branded queries only show baseline entity recognition. You must test category understanding, vendor comparisons, use-case constraints, risk factors, and purchase decisions to evaluate performance across the entire buyer journey.
Can a composite visibility score serve as a KPI?
A single score can serve as a broad executive summary, but never as an operational metric. You must preserve the underlying log data; otherwise, you cannot separate mentions from citations, factual accuracy, or qualified traffic.
Does failing to appear in a single prompt mean optimization failed?
Not necessarily. Check the prompt version, testing parameters, crawl status, and historical data first, then evaluate the performance using a stable, long-term sample set.
Does getting cited in the sources mean the test passed?
No. You must click the URL to verify that the page loads, that the body copy actually supports the AI's claims, and that the entity information is current.
Why is AI referral traffic often undercounted?
Different AI tools and browsing modes strip or modify referrer data inconsistently. Document what your analytics can verify, treat unclassified traffic as a tracking limitation, and avoid estimating unverified numbers.
How much content should change in a single iteration?
There is no fixed limit. The rule is that all edits in a round must test a single hypothesis, backed by a changelog detailing what changed, why, and what outcome to measure during re-testing.
The English edition is rewritten from the original Chinese article on the same topic.

Starbox AI is an AI marketing company based in Hangzhou, China. This article draws on Starbox project work. Please credit the source when quoting.
Related reading
 GEO Guide
Why AI Marketing Vendor Quotes Vary 10x: A 4-Step Vetting Checklist
Evaluate AI marketing proposals by delivery actions, not slide decks. Audit source infrastructure, fact cleaning, and clean-environment testing.
Oct 22, 2026 · 6 min read
 GEO Guide
Spotting GEO Scams: What Actually Drives AI Recommendations?
Automated AI ranking promises violate how LLMs work. Real AI recommendations rely on authoritative, structured facts across trusted public sources.
Oct 22, 2026 · 4 min read
 GEO Guide
How to Measure Your Brand's AI Visibility with a Spreadsheet
You do not need expensive software to track AI recommendations. A three-tier prompt framework and a simple spreadsheet can score your brand visibility in half a day.
Oct 21, 2026 · 6 min read